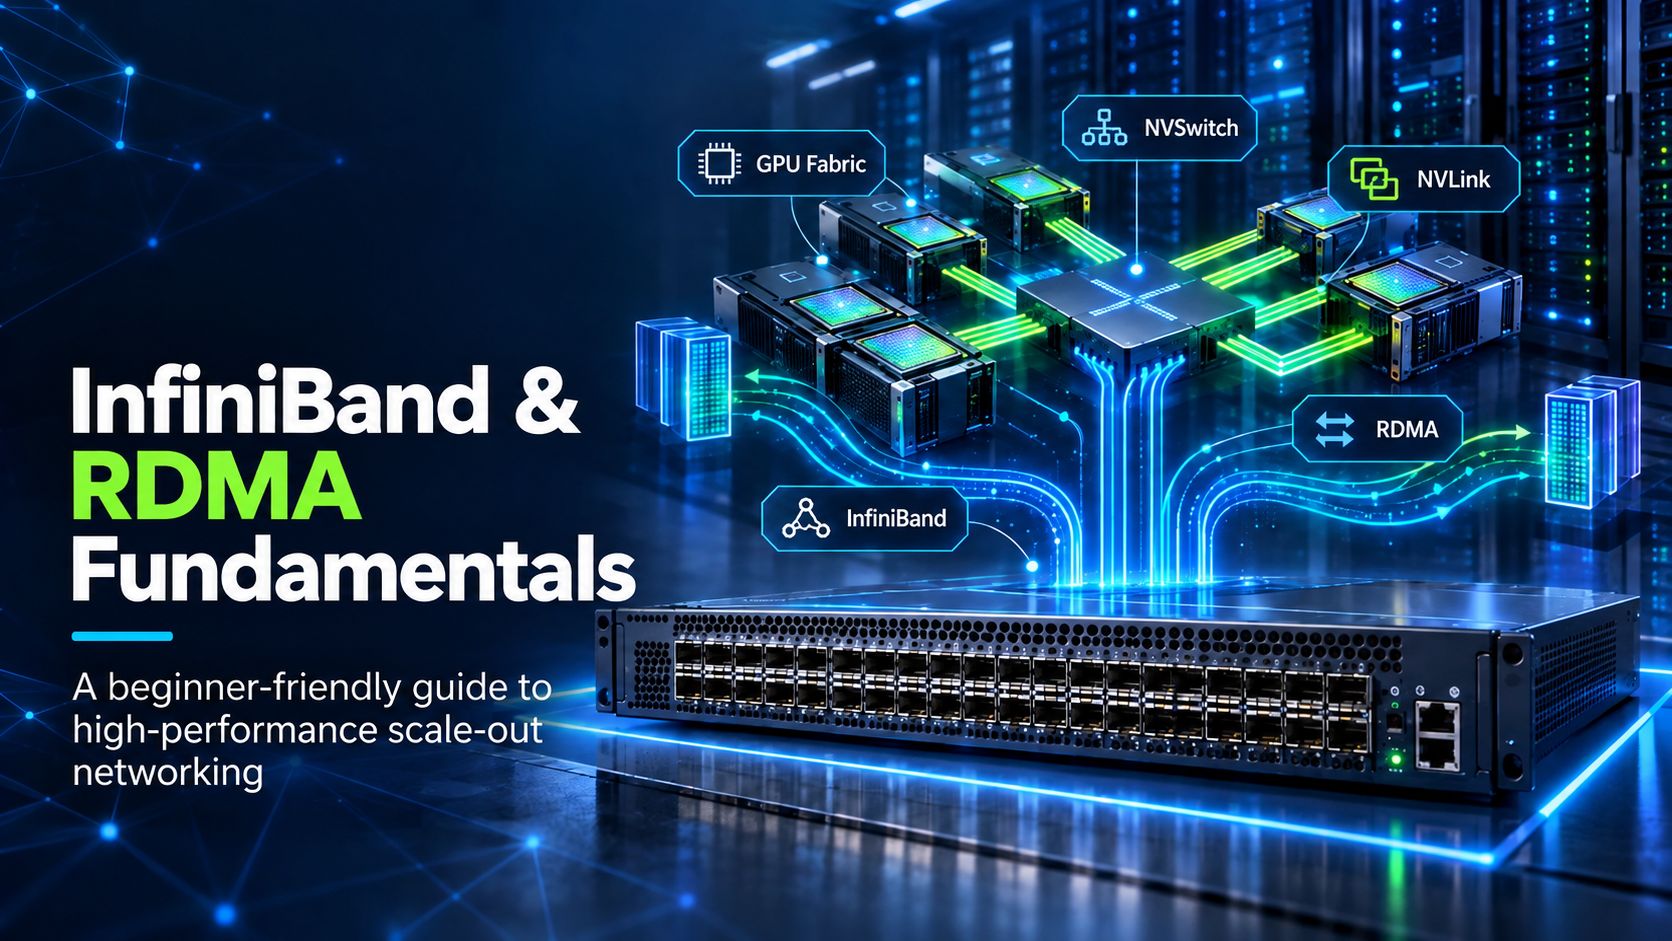
Conventional Ethernet is an extraordinarily flexible general-purpose network. InfiniBand is a specialized fabric with native RDMA transports, subnet management, credit-based flow control and an HPC-oriented software ecosystem. The comparison is therefore not simply “which cable is faster?” but “which operational and transport model best matches the cluster?”
Table 18. InfiniBand versus RoCEv2
| Dimension | InfiniBand | RoCEv2 |
| Underlying network | InfiniBand switched fabric | Ethernet/IP/UDP fabric |
| RDMA semantics | Native | Native RDMA semantics carried over Ethernet |
| Control/routing model | InfiniBand SM/subnet concepts | Ethernet switching + IP routing/ECMP |
| Loss handling | Credit-based IB fabric behavior | Ethernet design must engineer loss/congestion carefully; often PFC/ECN-based approaches |
| Operational familiarity | Specialized HPC/AI skill set | Leverages Ethernet skill/tooling |
| Multi-purpose use | Primarily compute/storage fabric | Can converge with broader Ethernet use cases |
| AI ecosystem | Very mature in NVIDIA HPC/AI deployments | Also a major AI-fabric choice; Spectrum-X is NVIDIA’s Ethernet/RoCE platform |
| Design trade-off | Purpose-built consistency and integrated fabric control | Ethernet flexibility/interoperability with more tuning variables |
RoCEv2 is not “slow InfiniBand.” It provides RDMA over a different network architecture. A well-engineered RoCE fabric can deliver excellent AI performance, but it requires the Ethernet congestion, routing and QoS design to be correct. Conversely, InfiniBand introduces specialized management and operational tooling that some organizations do not already possess.
NVIDIA Spectrum-X is an Ethernet/RoCE AI-fabric approach, not InfiniBand. It exists because many operators want Ethernet interoperability while still optimizing for accelerator-scale communication. It is useful context when choosing an AI fabric, but it should not be used to redefine InfiniBand concepts.
Table 19. Scale-up versus scale-out interconnect
| Technology | Typical scope | Primary role |
| PCIe | Within a server / chassis I/O hierarchy | Connect CPUs, GPUs, NICs, storage devices |
| NVLink/NVSwitch | GPU scale-up domain | High-bandwidth GPU-to-GPU and accelerator interconnect |
| InfiniBand | Between servers / racks / cluster | Scale-out CPU/GPU communication and RDMA |
| COMMON MISTAKE: NVLink does not eliminate the need for a scale-out network when the workload spans multiple systems. It makes each node’s internal accelerator domain faster; InfiniBand connects those domains. |
Table 22. Architecture decision checklist
| Decision area | Questions to ask |
| Workload | MPI-heavy? NCCL-heavy? all-to-all? storage traffic? inference or training? |
| Scale | How many nodes/GPUs now and at growth target? |
| Per-node injection | How many HCA ports and what nominal bandwidth per node? |
| Topology | Non-blocking, oversubscribed, dual rail, rail-optimized? |
| Switch radix | How many tiers and how much port fragmentation/breakout? |
| Physical design | Copper/optics, cable distances, rack density, serviceability? |
| Availability | What link/switch/SM failures must jobs survive? |
| Software stack | Kernel, rdma-core/DOCA-OFED, UCX, MPI, NCCL versions? |
| Locality | How are GPUs, HCAs, CPUs and PCIe roots arranged? |
| Operations | Who owns SM, UFM/telemetry, firmware and troubleshooting? |
| Security | Partitions, management access, host hardening, tenancy assumptions? |
| Cost | Switches, adapters, cables/optics, licenses, power, operations? |
| IMPORTANT: InfiniBand is powerful, not magical. |
Table 23. Misconception corrections
| Misconception | Correction |
| “RDMA means no CPU is involved anywhere.” | The control path, setup, memory registration and application logic still use CPUs/OS services. RDMA mainly reduces per-transfer fast-path work. |
| “InfiniBand and RDMA are the same thing.” | InfiniBand is a fabric architecture; RDMA is a communication capability also available over RoCE and iWARP. |
| “InfiniBand uses IP addresses just like Ethernet.” | Native IB forwarding uses its own identities such as LIDs/GIDs. IPoIB can carry IP, but that is an upper-layer service. |
| “Lossless means congestion cannot occur.” | Credits prevent buffer overrun; they can also propagate backpressure. Congestion remains a performance problem. |
| “400 or 800 Gb/s means my application gets that number.” | Payload efficiency, PCIe, memory, topology and message size determine observed throughput. |
| “NVLink replaces InfiniBand.” | NVLink is primarily scale-up; InfiniBand is a scale-out cluster fabric. |
| “InfiniBand is only faster Ethernet.” | It has a different addressing, subnet-management, transport and flow-control architecture. |
| “One-sided RDMA means the remote application has no role.” | The remote side must provision and authorize memory and coordinate semantics. |
| “GPUDirect RDMA means GPU-to-GPU cables.” | The HCA and switched network still carry the traffic; GPUDirect changes memory/I/O access paths. |
| “A non-blocking topology guarantees perfect scaling.” | Endpoint, routing, collectives, software and synchronization can still bottleneck. |
| “More rails always make every workload faster.” | Software must use them effectively; extra rails can add cost, path imbalance and complexity. |
| “The Subnet Manager forwards all traffic.” | It discovers/configures the subnet; switches forward data packets. |